Latest AI Resources

Total 3185 articles posts
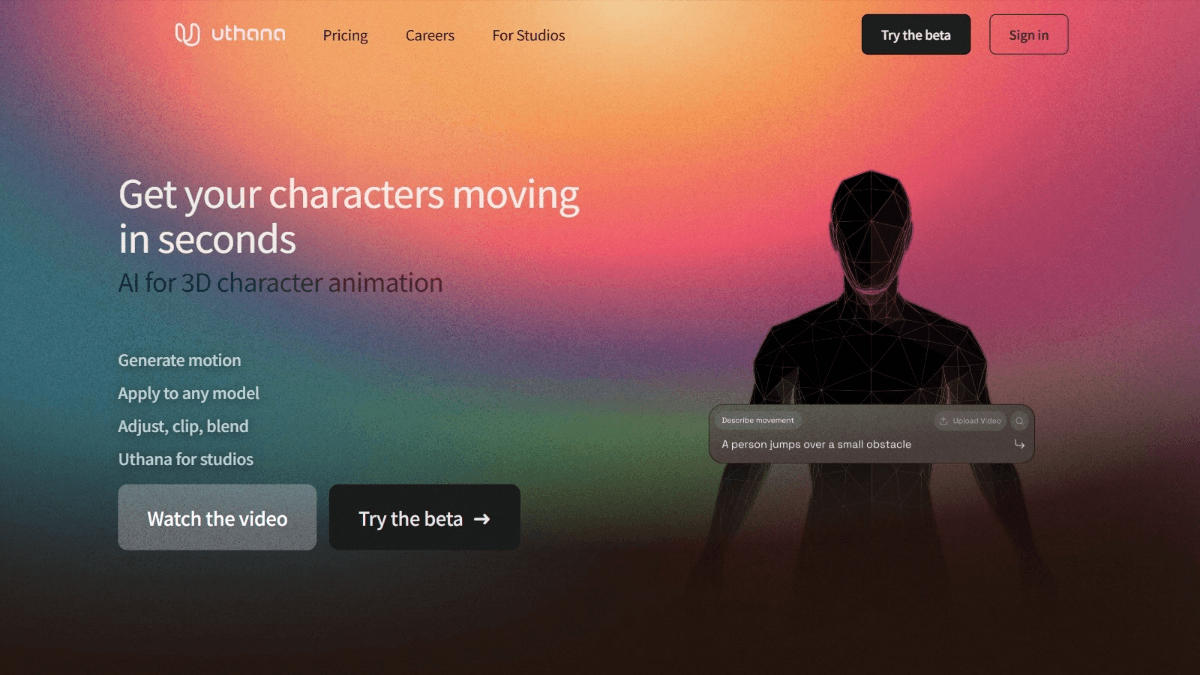
Uthana - AI 3D 角色动画生成平台,文字描述或参考视频生成逼真动画

Uthana - AI 3D character animation generation platform, text description or reference video to generate realistic animation

Uthana is a powerful AI 3D character animation generation platform. Users can input text descriptions, upload reference videos, or search motion libraries, and AI can quickly generate realistic animations and support adapting models with any bone structure. The platform is equipped with a variety of features such as style migration, API integration, customization...
1yrs ago
077.4K
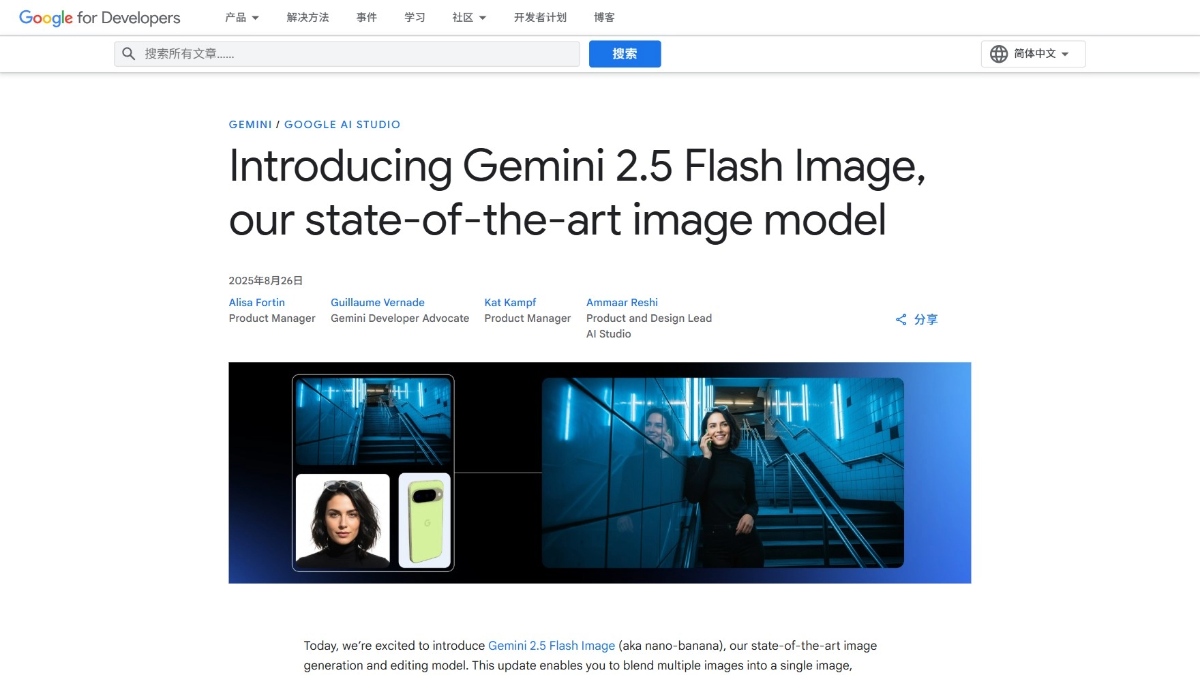
Doppl - 谷歌推出的AI虚拟试衣应用

Doppl - AI virtual fitting app from Google

Doppl is an AI virtual fitting application launched by Google. After the user uploads a full body photo, the application supports the clothing picture or screenshot "wear" in the digital version of their own body, and can be converted from static pictures to AI-generated video, so that users can more truly feel the effect of clothing on the body.
1yrs ago
077.4K
LongCat-Video - 美团LongCat开源的视频生成模型

LongCat-Video - LongCat open source video generation model of the Mission

LongCat-Video is a 1.36 billion parameter video generation model open source by the LongCat team, using the MIT open source protocol, supporting three major tasks: text-generated video, graph-generated video and video continuation. The model through the "coarse to fine" generation strategy and block sparse attention mechanism, can be in a number of minutes ...
11mos ago
077.3K
商汤如影 - 商汤科技推出的AI数字人视频制作平台

Shangtang Ruyi - AI digital human video production platform launched by Shangtang Technology

Shangtang Ruying is an AI digital human video production platform launched by Shangtang Technology. Based on big model technology, the platform supports the creation of highly realistic digital human images and personalization, including facial features, clothing, hairstyles, and so on. The platform is equipped with sound cloning, video generation, automated data labeling, real-time interaction, and other functions...
1yrs ago
077.3K
VoxCPM 1.5 - 面壁智能开源的端到端文本到语音模型

VoxCPM 1.5 - Faceted Intelligence Open Source End-to-End Text-to-Speech Modeling

VoxCPM 1.5 is an open source speech generation model released by Facade Intelligence, based on text-to-speech (TTS) technology without the need for a splitter, featuring several innovations and improvements. Adopting an end-to-end diffusion autoregressive architecture, it generates continuous speech waveforms directly from text, avoiding the limitations of traditional segmentation methods...
9mos ago
077.2K
ChatGPT Agent – OpenAI推出的通用智能AI Agent

ChatGPT Agent - General Intelligence AI Agent by OpenAI

ChatGPT Agent is a general-purpose AI Agent from OpenAI that combines multiple capabilities to autonomously accomplish complex tasks. Users only need to describe their needs in natural language, and the Agent can automatically select the appropriate tools, such as browsing the web, extracting information, running code...
1yrs ago
077.2K
SkyReels-A3 - 昆仑万维推出的音频驱动数字人创作工具

SkyReels-A3 - Audio-Driven Digital Human Creation Tool from KunlunWangwei

SkyReels-A3 is an audio-driven digital human creation tool from Kunlun World Wide Group. SkyReels-A3 is an audio-driven digital human creation tool, which can generate high-quality dynamic video content through simple inputs (e.g., portrait images and voice), make static photos "come alive", and replace lines for existing videos with new lip-syncs that the characters will automatically...
1yrs ago
077.1K
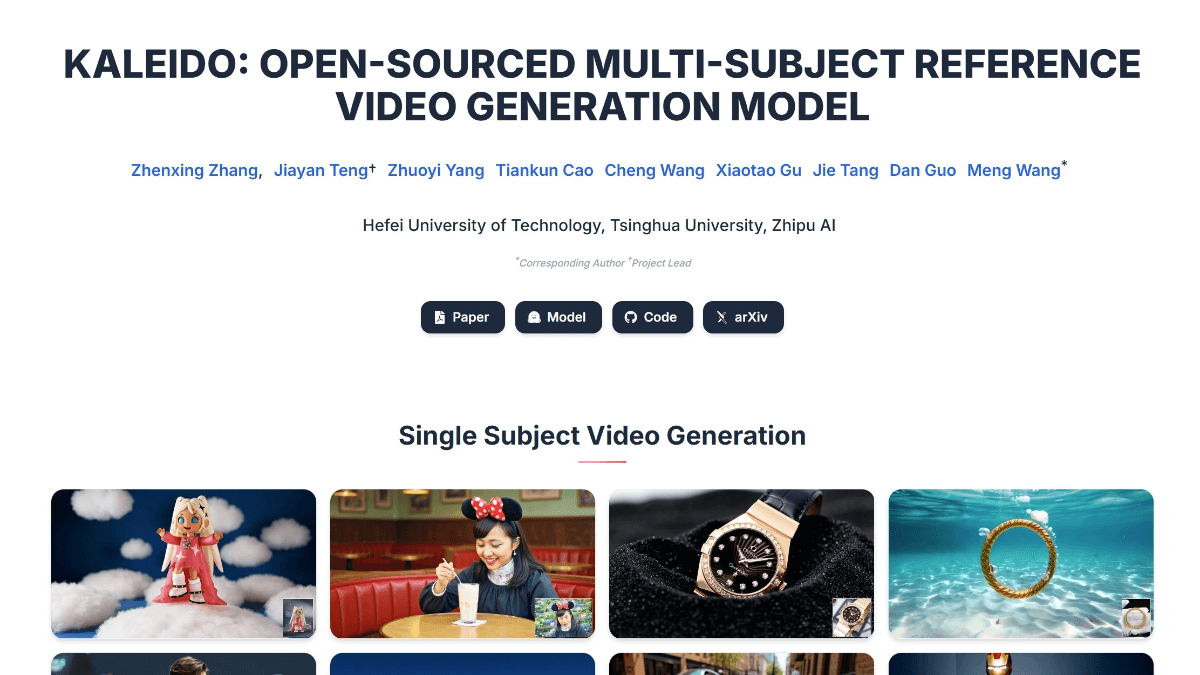
Kaleido - 智谱AI联合清华大学等开源的多主体参考视频生成模型

Kaleido - A multi-subject reference video generation model open-sourced by Smart Spectrum AI in collaboration with Tsinghua University and others

Kaleido is an open source multi-subject reference video generation model jointly developed by Hefei University of Technology, Tsinghua University and Smart Spectrum AI. It generates subject-consistent videos through multiple reference images, solving the deficiencies of existing models in multi-subject consistency and background decoupling.Kaleido generates videos through specialized data...
9mos ago
076.7K
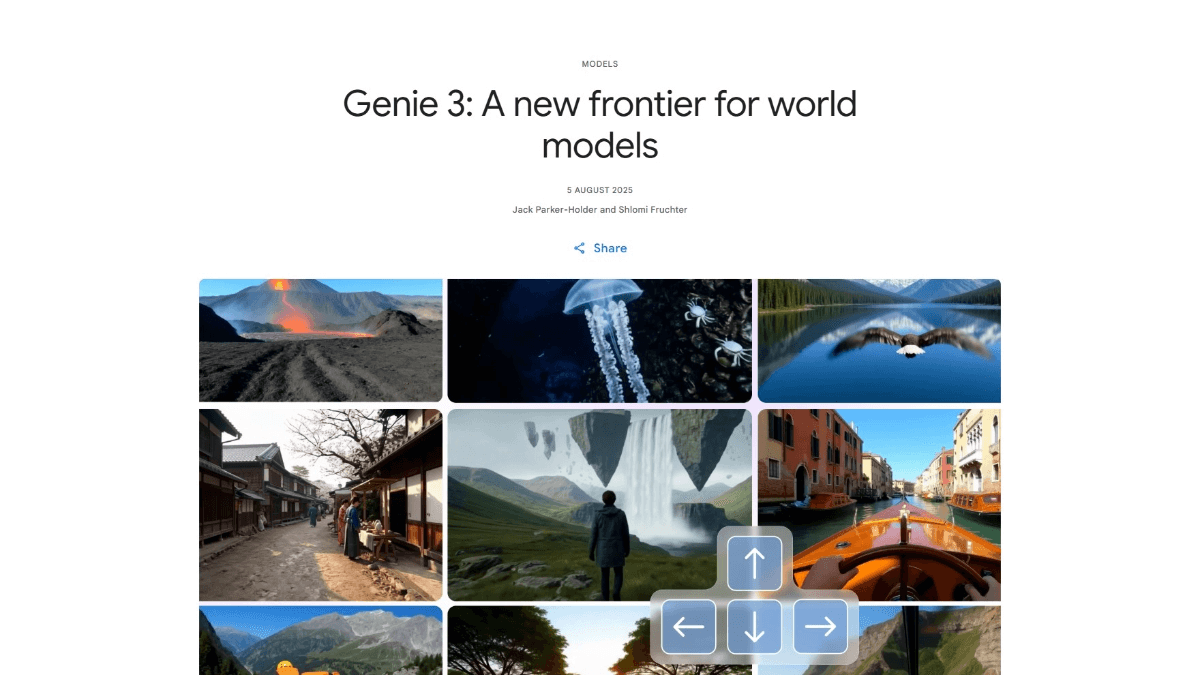
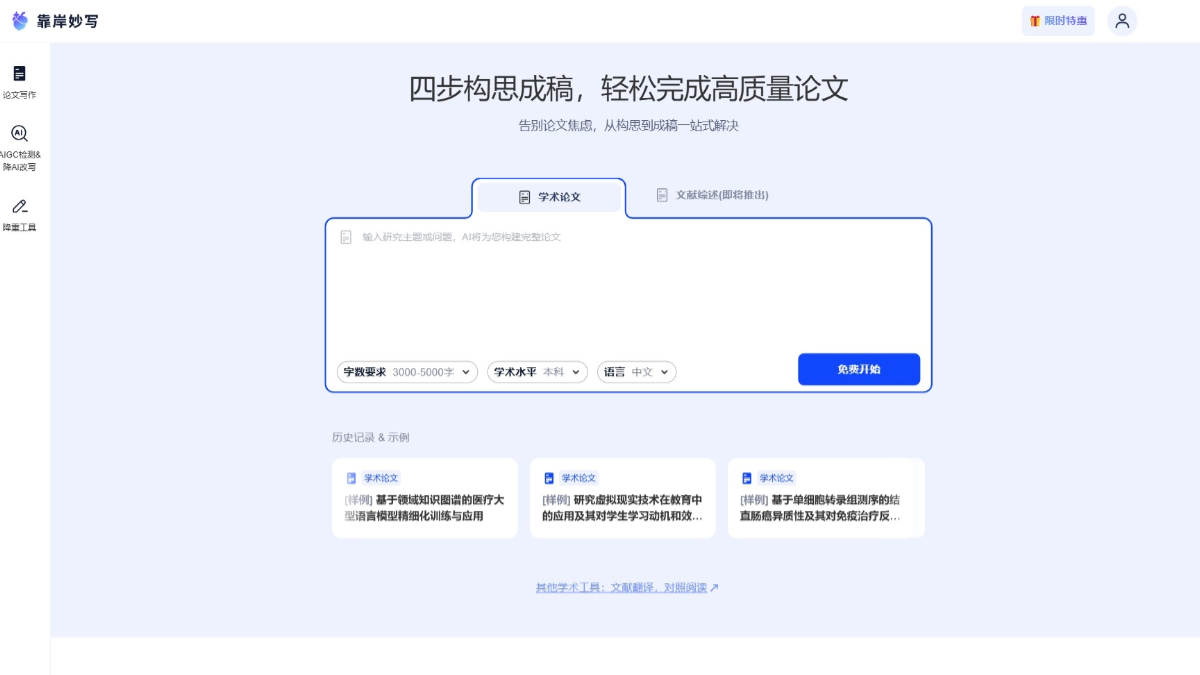
Genie 3 - 谷歌推出的通用世界模型

Genie 3 - A Universal World Model from Google

Genie 3 is a next-generation universal world model from Google DeepMind that enables the generation of highly dynamic and coherent virtual worlds in real time.Genie 3 simulates physical phenomena, natural ecosystems, and supports the creation of fantasy and historical scenarios. With text prompts, users can...
1yrs ago
076.7K
Higress MCP - 今日投资推出的MCP服务平台

Higress MCP - Invest Today Launches MCP Services Platform

Higress MCP is an innovative platform launched by Invest Today that supports the rapid transformation of traditional financial data APIs into modern MCP services.Higress MCP enables the transformation of REST APIs to MCP Server based on a simple configuration without the need to program...
1yrs ago
076.7K
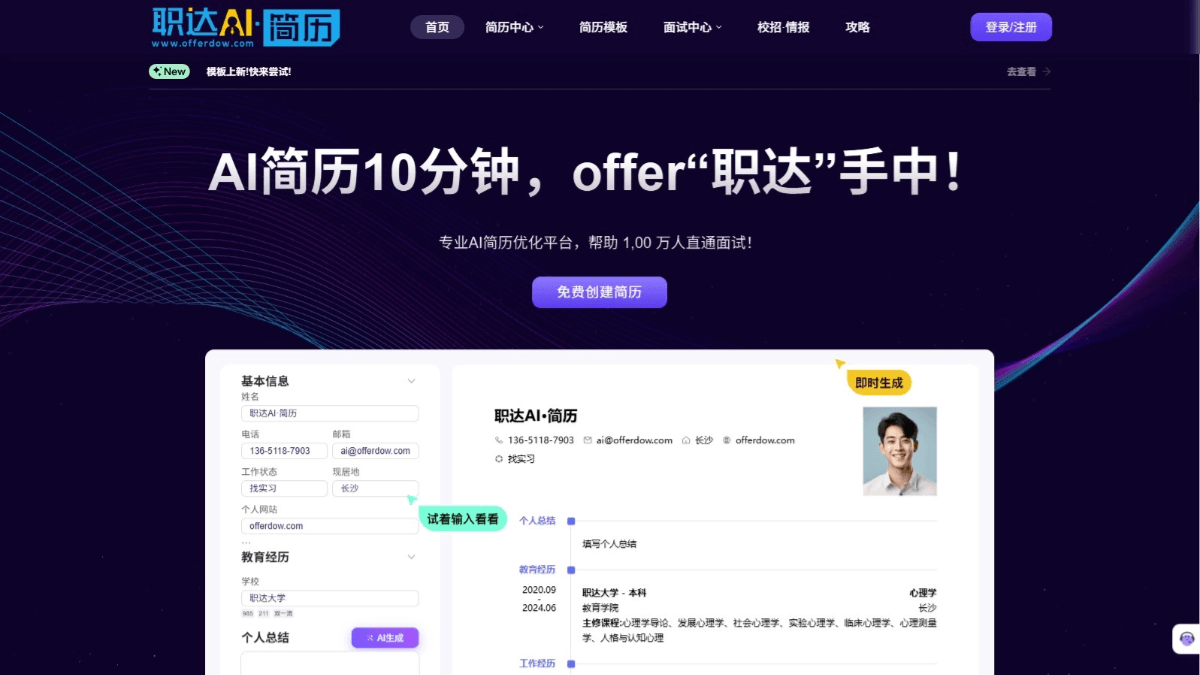
职达AI简历 - AI简历生成与优化平台,精准分析问题、提供优化建议

Vinda AI Resume - AI Resume Generation and Optimization Platform, Precise Analysis of Problems and Optimization Suggestions

Job AI resume is an efficient and convenient intelligent resume generation and optimization platform. Based on AI technology, the platform helps users quickly generate professional and personalized resumes. Users only need to enter basic information and experience, the platform can generate high-quality resume in a short time, providing 2800+ beautiful templates, covering a variety of positions.
1yrs ago
076.6K
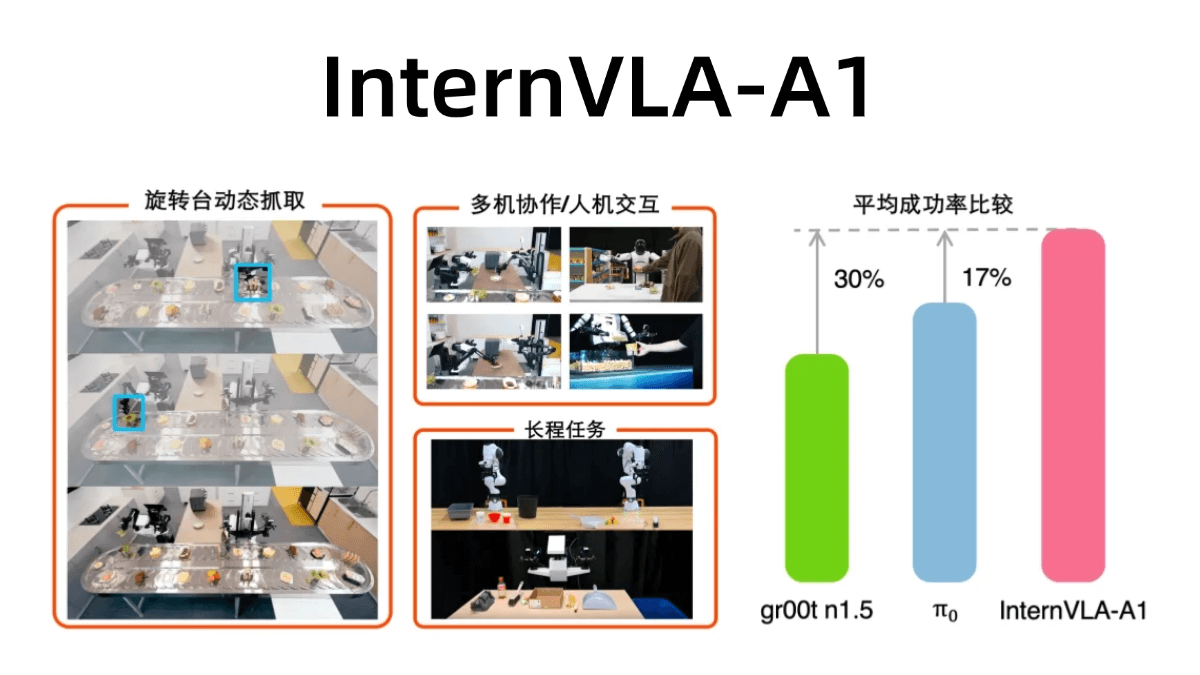
InternVLA-A1 - 上海AI Lab开源一体化操作能力的具身大模型

InternVLA-A1 - Shanghai AI Lab Open Source Integration of Operational Capabilities for Embodied Large Models

InternVLA-A1 is a large model of embodied operation open-sourced by Shanghai Artificial Intelligence Laboratory. It has the ability to understand, imagine, and execute the integration, and can accurately complete the task. The model fuses real and simulated operational data, and automates the construction of massive multimodal through large-scale virtual-real hybrid scene assets...
1yrs ago
076.5K
gpt-realtime - OpenAI最新推出的AI语音模型

gpt-realtime - OpenAI's newest AI speech model

gpt-realtime is an advanced speech model from OpenAI that supports direct audio processing to generate natural and smooth speech. The model supports multiple languages and styles, understands non-verbal cues such as laughter, and can switch between languages.
1yrs ago
076.2K
靠岸妙写 - AI论文写作工具,构思到成稿一站式解决

Leaning Wonderful Writer - AI essay writing tool, one-stop solution from idea to finished paper

Leaning Wonderful Writer is an AI dissertation writing tool that provides an efficient and convenient solution for academic writing. The tool supports one-click generation of dissertation outlines, abstracts and first drafts of the body of the paper, which is applicable to different levels of academic needs such as undergraduate and master's degrees, and covers multi-disciplinary fields such as science and technology, liberal arts and social sciences.
1yrs ago
076.1K
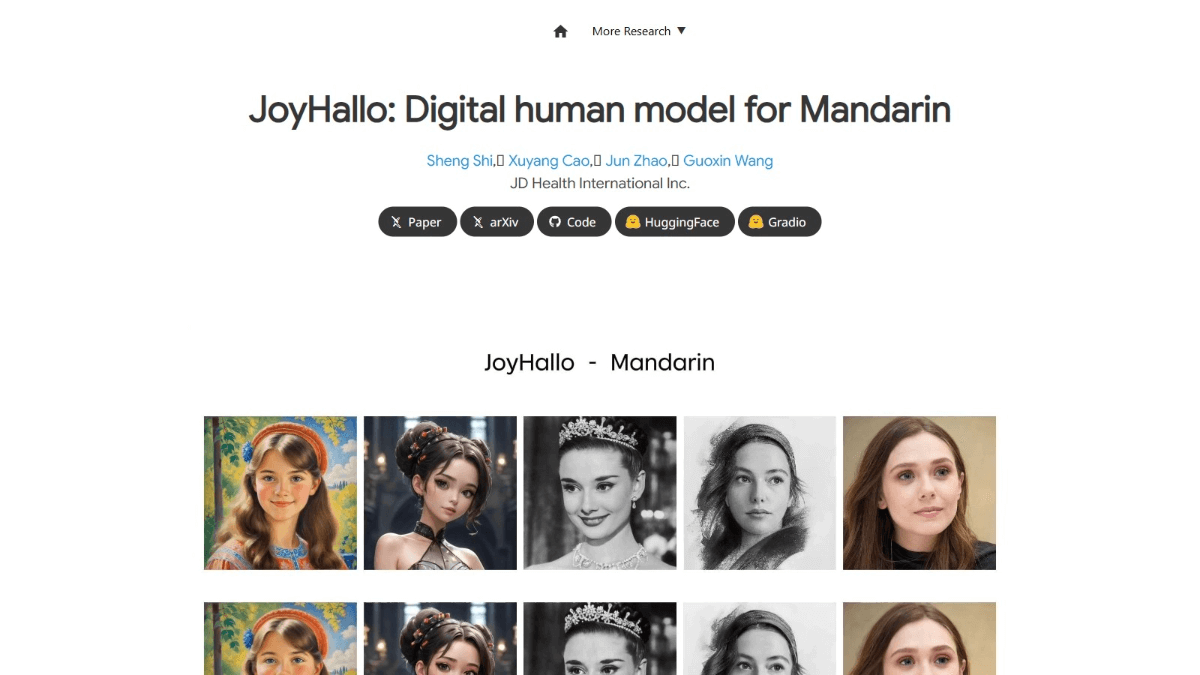
JoyHallo - 京东开源的AI数字人模型

JoyHallo - Jingdong's open source AI digital human model

JoyHallo is an open source AI digital human model from Jingdong, designed for Mandarin, supporting the conversion of audio into realistic speaking video.JoyHallo embeds audio features based on the wav2vec2 model, using a semi-decoupled structure to improve the accuracy of lip movement prediction, and supports the generation of English video...
1yrs ago
076K
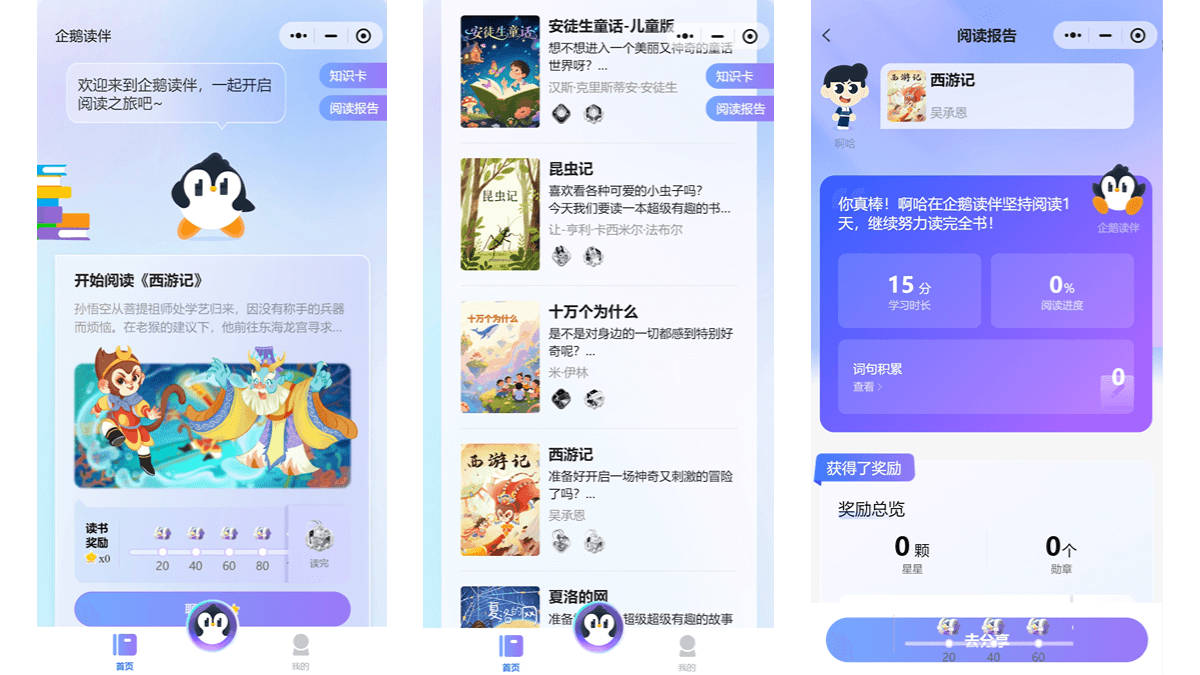
企鹅读伴 - 腾讯推出的中小学生AI阅读助手

Penguin Reading Companion - Tencent's AI Reading Assistant for Primary and Secondary School Students

Penguin Reading Companion is an AI reading assistant designed for primary and secondary school students by Tencent. Penguin Reading Companion relies on Tencent's hybrid big model and metamachine platform, combined with the Compulsory Education Language Curriculum Program and Curriculum Standards (2022 Edition), to provide students with personalized reading recommendations, multiple reading modes (focusing, reading aloud, listening...
1yrs ago
075.9K
MiniMax Music 1.5 - MiniMax最新推出的AI音乐生成模型

MiniMax Music 1.5 - MiniMax's latest AI music generation model

MiniMax Music 1.5 is an advanced AI music generation tool that supports generating up to 4 minutes of music based on users' natural language descriptions. The model supports a variety of music styles and mood customization, generating a natural and full vocal color, smooth transitions, richly layered arrangements...
1yrs ago
075.7K
Goedel-Prover-V2 - 普林斯顿联合清华和英伟达等开源的定理证明模型

Goedel-Prover-V2 - Princeton's open-source theorem proving model in conjunction with Tsinghua and NVIDIA, among others

Goedel-Prover-V2 is an open-source theorem proving model jointly released by leading organizations such as Princeton University, Tsinghua University, and NVIDIA. The model is based on innovative techniques such as hierarchical data synthesis, verifier-guided self-correction, and model averaging to significantly improve the performance of automated formal proofs...
1yrs ago
075.4K
MoE-TTS - 昆仑万维推出的最新语音生成框架

MoE-TTS - The Latest Speech Generation Framework from KunlunWei

MoE-TTS is a speech synthesis framework introduced by KunlunWanwei, based on the Mixed Expert (MoE) architecture, which combines pre-trained Large Language Models (LLMs) with speech expert modules.MoE-TTS retains the powerful textual reasoning by freezing the textual module parameters and updating only the speech module parameters...
1yrs ago
075.2K
Seed GR-3 - 字节跳动Seed团队推出的通用机器人模型

Seed GR-3 - Generalized Robotics Model from the Wordpress Seed Team

Seed GR-3 is a general-purpose robot model introduced by ByteDance with strong generalization ability to adapt to new environments and complex commands. The model fuses visual, verbal, and motion information, and is based on a three-in-one training method of robot data, VR human trajectory data, and publicly available graphic data to enhance the ability to respond to new objects...
1yrs ago
075.2K
Ovis-U1 - 阿里推出的多模态统一AI模型

Ovis-U1 - Multimodal Unified AI Model Introduced by Ali

Ovis-U1 is a multimodal unified model introduced by the Ovis team of Alibaba Group with a parameter scale of 3 billion. The model is equipped with three core capabilities: multimodal understanding, text-to-image generation, and image editing. With advanced architectural design and collaborative and unified training methods, the model supports the realization of high-fidelity image...
1yrs ago
075.1K
EXAONE 4.0 - LG推出的混合推理模型

EXAONE 4.0 - Hybrid Reasoning Model introduced by LG

EXAONE 4.0 is a hybrid reasoning grand model from LG AI Research in Korea, blending general-purpose natural language processing and advanced reasoning capabilities. The model supports Korean, English, and Spanish, and is divided into a 32B professional version and a 1.2B end-side version. The professional version is suitable for legal, accounting...
1yrs ago
075K
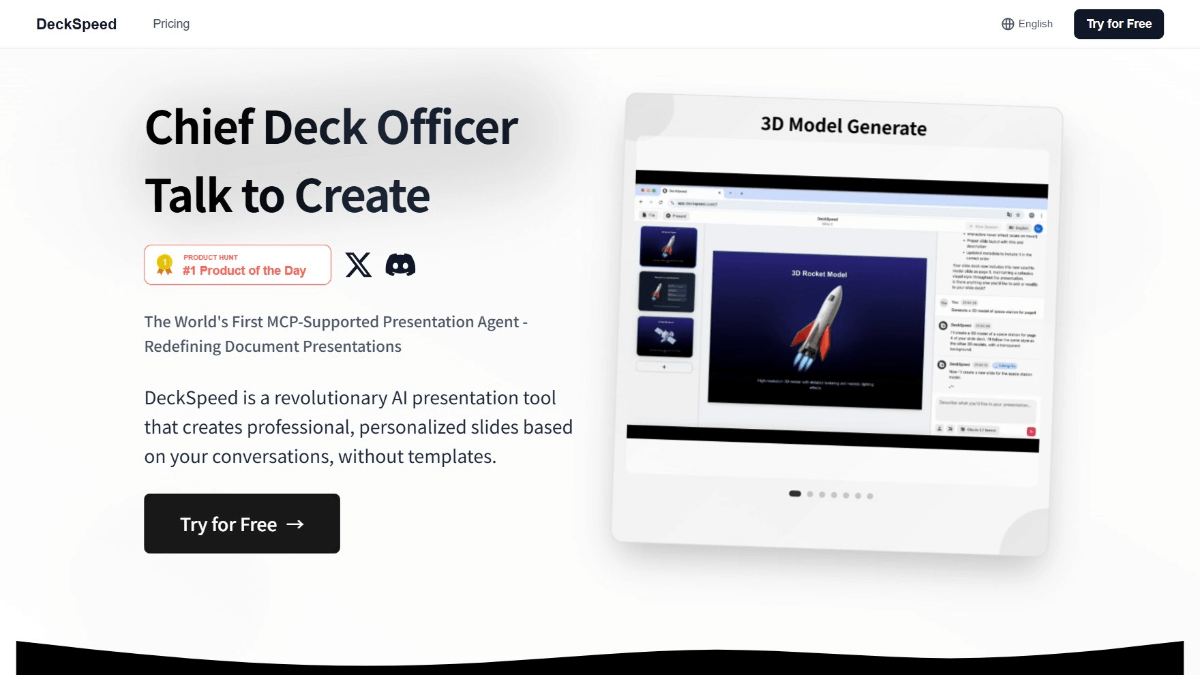
DeckSpeed - AI PPT制作工具,自然语言生成演示文稿

DeckSpeed - AI PPT Maker, Natural Language Generated Presentation

DeckSpeed is an AI presentation creation tool based on conversational interaction, where users express their needs based on natural language and quickly generate personalized slides without relying on traditional templates. The tool supports real-time feedback adjustment, users can modify the color, style and content of the slide at any time to ensure that the presentation is complete...
1yrs ago
074.9K
CRIC深度智联 - 克而瑞推出的中国房地产首个AI Agent

CRIC - The First AI Agent for Real Estate in China Launched by CRIC

CRIC Depth Intelligence is the first AI intelligent body of Chinese real estate independently developed by CRIC, based on CRIC's 20 years of experience in the real estate industry and data accumulation and multimodal big model technology, which opens up the whole chain from data integration, intelligent analysis to content generation.
1yrs ago
074K
ThinkSound - 阿里通义推出的音频生成模型

ThinkSound - Audio Generation Model launched by Ali Tongyi

ThinkSound is the first CoT (Chain Thinking) audio generation model introduced by Ali Tongyi's speech team. The model can generate accurately matched sound effects for video images, based on the introduction of CoT reasoning, to solve the problem of traditional technology is difficult to capture the dynamic details of the screen and spatial relationships.
1yrs ago
074K
稿定AI社区 - AI创意内容设计平台,多种设计资源满足不同创作需求

Drafting AI Community - AI creative content design platform, a variety of design resources to meet different creative needs

Drafting AI Community is an online AI creative inspiration platform that provides users with a wealth of creative design resources and tools. The platform covers a variety of design fields, including image photos, e-commerce design, holiday themes, 3D illustrations, avatar design, Xiaohongshu materials, portrait design, etc., to meet the needs of different users.
1yrs ago
074K
AutoMV - M-A-P联合北邮、南大等开源的免费音乐视频生成系统

AutoMV - M-A-P open source free music video generation system in conjunction with the North Post, South University, etc.

AutoMV is an open source music video generation system developed by the M-A-P team in collaboration with several universities, which can automatically generate coherent music videos based on complete songs without training.It adopts a multi-intelligence body collaboration model, including music analysis, scriptwriting, directing, and quality control modules, and can accurately analyze the lyrics, beats, and...
9mos ago
073.9K
CWM - Meta FAIR开源的代码世界语言模型

CWM - Meta FAIR open source code world language model

CWM (Code World Model) is a 32-billion-parameter open-source world language model released by the Meta FAIR team, designed for code generation and reasoning. Introducing the concept of "world model", it can simulate the code execution process, predict the variable state changes, and advance...
12mos ago
073.9K
MedASR - 谷歌开源的医疗语音识别模型

MedASR - Google's open source medical speech recognition model

MedASR is a 105 million parameter medical speech recognition model open-sourced by Google, fine-tuned on a 5,000-hour desensitized clinical corpus, optimized for drug, dosage, and anatomical terminology, with a built-in 6-gram medical language model, and a word error rate of only 4.6 on the private radiology dataset RAD-DICT...
9mos ago
073.4K
Step-Audio 2 mini - 阶跃星辰开源的语音大模型

Step-Audio 2 mini - Step-Star Open Source Speech Megamodels

Step-Audio 2 mini is an open source end-to-end speech grand model of Step-Audio. It breaks through the traditional speech model structure and adopts the true end-to-end multimodal architecture, which directly transforms the original audio input into speech response output with lower latency, and understands paralinguistic information and non-vocal signals.
1yrs ago
072.6K